Against calibration [againstcalibration]
Against calibration [againstcalibration]
Forecasting is predicting whether something will happen, like who will be the next US president or whether a natural disaster will happen or what the economy is going to be like in a year. It's notoriously difficult to think about. Typically who study this sort of thing think you should make quantifiable predictions with specific probabilities assigned to them, make them public, and then let people rate your performance later to figure out who's good at forecasting. I'm not gonna explain all this in too much detail. See eg the discussion at the start of this astralcodexten post.
One way to rate forecasts is "Brier score".[^2] If you assign something probability p, and it happens, your Brier score is (1-p)^2. If it doesn't happen, your Brier score is p^2 (since you essentially said it wouldn't happen with probability 1-p). Lower is better - the lowest possible Brier score is 0, the highest is 1. If you make many predictions, your Brier score is the average Brier score across the whole set of questions.
Another way to rate forecasters is "calibration". Calibration looks at the fraction of your "X% likely" predictions that occurred, and asks how close that fraction is to X% (for each X). Then you can plot it in graphs like this (source: Manifold on twitter):
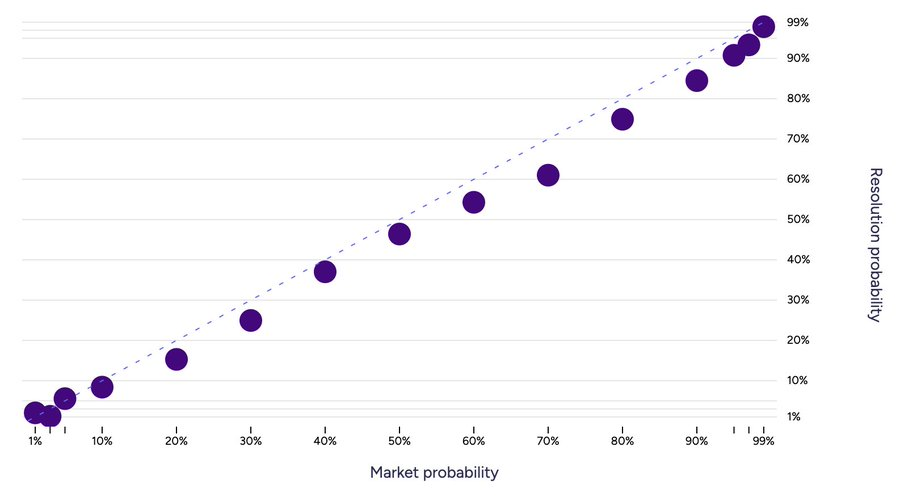
On average, clearly, 10% of your 10% predictions should come true if you're assigning probabilities sensibly, so it seems good to have good calibration. Brier scoring agrees with this, in the following sense: suppose in fact 14% of your 10% predictions come true. Then you would have obtained a higher Brier score by replacing all your 10% predictions with 14%[^1].
[^1]: This is essentially what people mean when they say Brier scoring is a "proper scoring rule".
There are a few reason people focus on calibration
- Perhaps most importantly, it's *comparable across question sets*. That is, if I make a bunch of predictions, and you make a *different set* of predictions, we can sensibly compare our calibration plots and see who did better. In contrast, predicting more difficult question sets will result in a lower Brier score even if you're doing as well as possible (in the limit, predicting coinflips, if you assign the correct 50-50 probability you'll get an average Brier score of 0.25, whereas if you predict events that happen 10% of the time and assign that probability correctly you'll get a Brier score of 0.09).
- There's some evidence that calibration is *trainable* and *generalizes.* That is, if you practice, you can improve your calibration, and if your calibration is good on one type of questions (say, about politics), it'll tend to be good on other questions (about technological advances, say) as well.
These obviously make calibration a pretty useful concept, and I don't want to disparage that. It's good to practice your calibration if you want to make precise predictions, and it's good to publish your calibration graph if you want people to take your forecast seriously.