Blog [efr-AE01]
Blog [efr-AE01]
A simple categorical proof of (a) Martingale Convergence Theorem [efr-5NUC]
A simple categorical proof of (a) Martingale Convergence Theorem [efr-5NUC]
This concept is essentially what is called a bilimit in domain theory and studied for embedding-projection pairs.
Against calibration [againstcalibration]
Against calibration [againstcalibration]
Forecasting is predicting whether something will happen, like who will be the next US president or whether a natural disaster will happen or what the economy is going to be like in a year. It's notoriously difficult to think about. Typically who study this sort of thing think you should make quantifiable predictions with specific probabilities assigned to them, make them public, and then let people rate your performance later to figure out who's good at forecasting. I'm not gonna explain all this in too much detail. See eg the discussion at the start of this astralcodexten post.
One way to rate forecasts is "Brier score".[^2] If you assign something probability p, and it happens, your Brier score is (1-p)^2. If it doesn't happen, your Brier score is p^2 (since you essentially said it wouldn't happen with probability 1-p). Lower is better - the lowest possible Brier score is 0, the highest is 1. If you make many predictions, your Brier score is the average Brier score across the whole set of questions.
Another way to rate forecasters is "calibration". Calibration looks at the fraction of your "X% likely" predictions that occurred, and asks how close that fraction is to X% (for each X). Then you can plot it in graphs like this (source: Manifold on twitter):
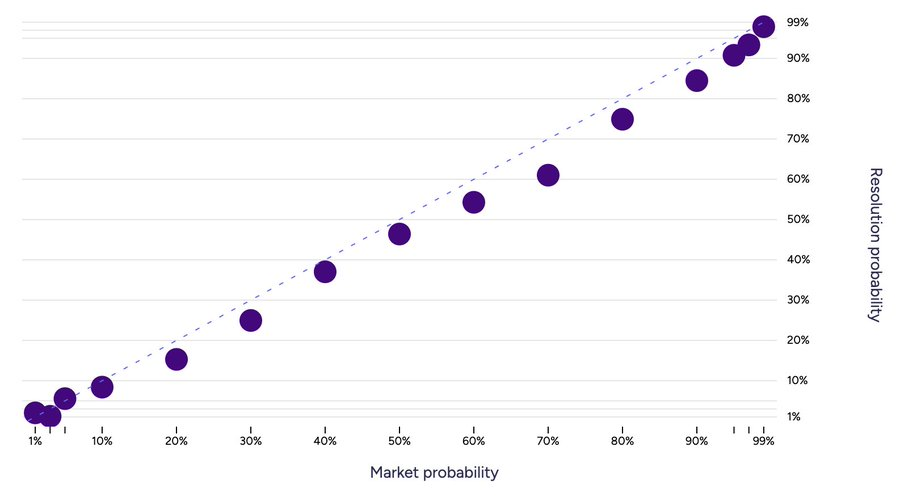
On average, clearly, 10% of your 10% predictions should come true if you're assigning probabilities sensibly, so it seems good to have good calibration. Brier scoring agrees with this, in the following sense: suppose in fact 14% of your 10% predictions come true. Then you would have obtained a higher Brier score by replacing all your 10% predictions with 14%[^1].
[^1]: This is essentially what people mean when they say Brier scoring is a "proper scoring rule".
There are a few reason people focus on calibration
- Perhaps most importantly, it's *comparable across question sets*. That is, if I make a bunch of predictions, and you make a *different set* of predictions, we can sensibly compare our calibration plots and see who did better. In contrast, predicting more difficult question sets will result in a lower Brier score even if you're doing as well as possible (in the limit, predicting coinflips, if you assign the correct 50-50 probability you'll get an average Brier score of 0.25, whereas if you predict events that happen 10% of the time and assign that probability correctly you'll get a Brier score of 0.09).
- There's some evidence that calibration is *trainable* and *generalizes.* That is, if you practice, you can improve your calibration, and if your calibration is good on one type of questions (say, about politics), it'll tend to be good on other questions (about technological advances, say) as well.
These obviously make calibration a pretty useful concept, and I don't want to disparage that. It's good to practice your calibration if you want to make precise predictions, and it's good to publish your calibration graph if you want people to take your forecast seriously.
Coproducts in the category of lenses [coprods-lens-blogpost]
Coproducts in the category of lenses [coprods-lens-blogpost]
The forwards part of this proof almost works for any distributive category \mathcal {C} with a *strict* initial object (meaning the only maps X \to 0 are isomorphisms, i.e X has to be another initial object). The trouble is that X_i \times C can be initial even when neither X_i nor C is, meaning even when A_i is initial and X_i isn't, the nonemptyness of \mathsf {Set}(X_i \times C, A_i) does not imply that C is initial, meaning that we don't automatically get that all the (\varphi _i^-)^* maps are bijections. A simple example of this is something like \mathcal {C} = \mathsf {Set}^k for some natural number k > 1. Then as long as we have C^{(n)} empty *or* X_i^{(n)} empty for each n = 1 \dots k, their product is empty.
A more general class of example with the same flavor is \mathcal {C} = Sh(X) the category of sheaves on a topological space. Then again as long as the supports of C and X_i are disjoint, their product is empty.
It may be possible to develop a generalization of the theorem, or at least of the forwards part of the theorem, using considerations like these to control the sets of morphisms.
Thoughts on the Kelly Criterion [kelly-betting]
Thoughts on the Kelly Criterion [kelly-betting]
(Epistemic status: contains some mildly sloppy math, but is essentially true).
Suppose someone offers you the chance to bet some money on a coinflip. On a heads, you multiply your stake by 3.75, but if you lose, you lose your stake. Should you bet, and how much? Clearly this bet has positive *expected value*, and higher expected value the more your bet, but equally clearly, the actual decision depends a lot on your circumstances - and you'd be a fool to bet your entire life savings on this, or to take out as large a loan as possible to gamble on it.
One way of thinking about a bet like this is the so-called Kelly criterion. It's a particular formula for how large a fraction of your total wealth you should bet (depending on the odds of the bet), with the following nice property: if you make an infinite sequence of bets at the same odds, and bet the Kelly at each opportunity, your total profit is eventually larger than any other betting strategy, with probability 1.
Since the Kelly criterion never bets its entire bankroll, but the EV-maximizing thing is always to bet your entire bankroll, some people take this to mean there's some fundamental flaw with EV in this case - that expected value is simply misapplied to one bet in a sequence like this. It's true that we have to be more careful here - if the thing we care about is our wealth after some sequence of N bets (N going to \infty ), we can't just assume that we should maximize EV after one bet. But if we try to maximize EV after N bets, we *still* find that the maximizing thing is to bet the entire bankroll every time. But how can this be true if the Kelly dominates every other strategy with probability 1? What's going on here?
---
One way you can justify evaluating bets by their expected value is this: suppose you will get many opportunities to take a given bet, and the way the payouts aggregate is additive - that is, your total “score” that you care about maximizing is the score from each independent instance of the bet added together. Then, assuming the variance of each bet outcome is not too heavy-tailed, as the number of bets goes to infinity, the distribution of the sums approximates a normal distribution with median NE and variance proportional to \sqrt {N}, where n is the number of bets and E is the expected value.[^1]
Since for large n the variance is much smaller than the expected value, the final outcome is more or less entirely determined by the expected value! This type of result is called a concentration theorem. This is a powerful justification for replacing a bet with its expected value, but only if bets combine additively!
For example, suppose the bet is something like “invest all your money in the stock market for a year”. You will get many opportunities to make this bet, but it’s not really appropriate to treat them additively - because, if you make a profit one year, you have more to invest next year, meaning you’ll be able to make an even bigger profit then, and vice versa if you lose.
Suppose a stock market investment has a 50% chance of multiplying your investment by 1.5, and a 50% chance of multiplying it by 0.6. This is positive expected value, but if you execute this investment many times, it’s not the case that with high probability you’ll increase your money by some amount - in fact, with high probability, your total amount of money will converge to 0!
We can prove this by noting that this bet aggregates by multiplication - your final score is the product of your initial bankroll, 1.5 for every win, and 0.6 for every loss. This means that the logarithm of your final score is the sum of the logarithm of your bankroll, log(1.5) for every win, and \log 0.6 for every loss. Hence by the concentration theorem discussed above, the logarithm will tend toward \frac {n (\log 1.5 - \log 0.6)}{2}, and since \log 1.5 - \log 0.6 = \log 0.9 is negative, this goes towards negative infinity, meaning your actual score must go to zero.
So IF the concentration theorem was your reason for taking EV seriously, you’re forced to work with expected log score in the case of multiplicative bets, which, if you do the math, leads you to the Kelly criterion for how much to bet each round.
BUT! Who says you should care about concentration theorems? The concentration theorem says there is at most a low probability that the log of your score is big - but if the log of your score is big, then your score must be really big! If you do the math, you’ll see that the expected value of a “bet everything every time” strategy with the odds above, given n bets, is 1.05^{n/2} - which goes to infinity as n does. Of course, clearly most of this EV must live in some very unlikely outcomes.
When economists bring out something like the Von Neumann-Morgenstern theorem to say that rational actions are described by maximizing EV of some “utility” random variable, they’re simply not invoking a concentration theorem, so saying “the concentration theorem doesn’t apply” is just not a useful knockdown, and it doesn’t mean that utility maximization theory fails to account for this type of repeated bets. Of course, utility theory doesn’t rule out the Kelly betting behavior either - Kelly betting is perfectly rational, explained by utility that’s logarithmic in money (or whatever the bet is being made in).
[^1]: The mean, that is to say the sum of the first n samples divided by n, always converges to the expected value with probability 1, this is "the law of large numbers". Of course maximizing x and maximizing x/n amounts to the same thing, but you probably should care about the fact that the variance is growing with n!
An approach to approximate category theory [approximate-categories]
An approach to approximate category theory [approximate-categories]
A number of different people have thought about ways to bring notions of approximation into category theory. There seem to be essentially two notions that one would like to express here:
1. The idea that a digram, while it may not quite commute, commutes *up to some specified tolerance \epsilon *
2. The idea that a mapping, while it may not quite preserve the relevant structures, preserves them *up to some specified tolerance \epsilon *.
The first idea is, at a basic level, captured by categories enriched in (some monoidal category of) metric spaces, whereas the other can be captured by categories enriched in some category of sets with a function S \to \mathbb {R}, again equipped with a monoidal product suitable for the purpose at hand.
Categories enriched in metric spaces can be weakened to the *metagories* of Tholen and Wang (link) - these are, essentially, graphs with an "area" measure A(f,g,h) \in [ 0,\infty ), defined whenever f:x \to y, g:y \to z and h: x \to z form the edges of a 2-simplex, satisfying some sort of resonable 2-dimensional analogue of the triangle inequality. The basic idea is that the area measure indicates the failure of the given triangle to commute. So if A(f,g,h) = 0, h is a suitable choice for g \circ f. The axioms correspond to unitality and associativity. They also imply that
1. The set of maps x \to y has a pseudometric[^1]
2. Composites in the sense above are well-defined up to distance zero, i.e given two choices of composite they have d(h,h') = 0.
Of course, given a category enriched in metric spaces, you can take A(f,g,h) = d(gf,h).
The second idea seems to be Paolo Perrone is discussing in this talk, calling categories like this "weighted categories".
I want to spell out here a common generalization of the two approaches to "quantitative category theory" that I haven't seen discussed anywhere else. I think, beyond the convenience of having a formalism capturing both ideas, it is in fact natural to do so - certain operations, natural to a category theorist, take you from one of these worlds to the other, in a way that's neatly described by this approach. That being said, there are still some issues, which I'll also discuss.
The basic approach is to consider a type of *filtered simplicial set*, i.e a functor \Delta ^{op} \times ([ 0, \infty ), \leq ) \to \mathsf {Set}. Let's write this as X([n],r) = X^{\leq r}[n]. We will probably want to assume that the maps X^{\leq r}[n] \to X^{\leq r'}[n] for r \leq r' are all injections. Such an object is almost the same thing as a simplicial set (defined by X^{\leq \infty }[n] = \mathop {\mathrm {colim}}_{r}X^{\leq r}[n]) where each simplex \sigma has an associated real number r(\sigma ) \in [ 0, \infty ), given by the first r where that simplex appears in X^{\leq r}[n] \subseteq X^{\leq \infty }[n], such that the face an degeneracy maps never increase r. This is not quite correct, because for each simplex the set of r such that \sigma \in X^{\leq r} can be either [ a, \infty ) or (a,\infty ) for some a. We will probably want to impose the further condition that it's always the former. This amounts to the claim that X^{\leq r}[n] is the intersection of X^{\leq r'} for all r' > r, which is a sort of sheaf condition.
Okay, so the basic setup now is that we have a simplicial set, where each simplex has some associated positive number. It will be useful to think of this as the *error* of the simplex. Let me give a few examples of this to illustrate how I want to use this structure:
1. Given a category enriched in metric sets \mathcal {C}, we can consider the filtered simplicial set where
- X^{\leq r}[0] = \operatorname {ob} \mathcal {C} for each r.
- X^{\leq r}[1] is the set of morphisms in \mathcal {C}, again regardless of r.
- X^{\leq r}[2] consists of triples f:x \to y, g: y \to z, h: x \to z so that d_{\mathcal {C}(x,z)}(gf,h) \leq r.
- Each X^{\leq r} is 2-coskeletal, i.e given a compatible boundary for a higher simplex, there is always a unique such simplex (at any given error level).
It's clear that this data characterized such a category up to equivalence, although it's not totally obvious how to characterize the subclass of filtered simplicial sets which have this form.
2. Given a category equipped with a *weight* in the sense of Perrone, i.e a number d(f) for each morphism such that d(1) = 0, d(fg) \leq d(f) + d(g), we can build a filtered simplicial set as follows:
- X^{\leq r}[0] is the set of objects, for all r.
- X^{\leq r}[1] is the set of morphisms with d(f) \leq r.
- X^{\leq r}[2] is the set of commuting triangles (f,g,h) with d(f),d(g),d(h) \leq r.
- Each filtration degree is coskeletal, as above.
Again, it's clear that we can pull out a category with a metric on it in a unique way from a filtered simplicial set like this.
Thus, you're supposed to interpret a 2-simplex in X^{\leq r}[2] as saying "this triangle commutes, at least at error tolerance r", a morphism in X^{\leq r}[1] as being "a morphism up to error/metric r". In principle you could also have objects with errors, and higher simplices with errors if you wanted to do higher-categorical stuff.
Let's think about what makes such a simplicial set suitable for use as a category. Recall that an ordinary simplicial set X is the nerve of a category if and only if every inner horn \Lambda ^{n}_{k} \to X has a unique filler, which is in turn equivalent to asking that horns of every dimension have unique fillers, or that the maps X[n] \to X[1] \times _{X[0]} X[1] \times _{X[0]} \dots \times _{X[0]} X[1] are all bijections.
In other words, this is about fillers for certain horns existing, and perhaps existing uniquely. The world of quantitative categories is a bit more complicated, for the essential reason that
Here is my attempt at a suitable definition. For each n, 0 \leq k \leq n, and r_{0}, \dots , r_{k-1},r_{k+1}, \dots r_{n}, let \Lambda ^n_{k}(r_{0},\dots r_{n}) be the filtered simplicial set given by a horn \Lambda _{k}^{n}, with the ith face for each i having value r_{i}, i.e appearing in \Lambda _{k}^{n}(r_{1},\dots r_{n})^{\leq r_{i}} but not before (with the lower-dimensional faces all having the maximal possible value given this).
Similarly define \Delta ^{n}(r_{0}, \dots r_{n}) (given a full list of n+1 values). Then we say a filtered simplicial set \mathcal {C} is a *approximation quasicategory* if, for every 0 < k < n, and each tuple r_{0}, \dots r_{k-1},r_{k+1}, \dots r_{n} every map \Lambda _{k}^{n}(r_{0}, \dots r_{n}) \to \mathcal {C} admits an extension along \Lambda _k^n(r_{0},\dots r_{n}) \to \Delta ^{n}(r_{0}, \dots r_{k-1}, \sum _{i \neq k} r_{i}, r_{k}, \dots r_{n}).
This obviously corresponds to the definition of quasicategory (aka \infty -category, weak Kan complex...), with the additional structure of the filtration incorporated in such a way that errors add when composing morphisms. This is perhaps a good time to note that one could also have combined errors with \operatorname {max} instead of \Sigma . This would have amounted to asking that each \mathcal {C}^{\leq \epsilon } be a quasicategory in itself. From a categorical point of view this condition is much more natural, but adding errors seem more natural from the point of view of metrics, incorporating the triangle identity.
It is not entirely clear to me whether requiring each filler to exist uniquely, rather than merely exist, captures the right notion of 1-category. The reason is that it demands that composites be unique, whereas we might expect (from our earlier look at metagories) that they should only be unique up to an induced metric-0 notion. I tend to think that it's more sensible to require this equivalence relation to be already quotiented out, to make that part of the definition of approximation quasicategory, but I'm not entirely decided on this point.
1. The category of morphisms [\mathcal {C},\mathcal {D}] in a metric-enriched category naturally acquires a nontrivial filtration in the morphisms (which are commutative diagrams).
2. Iterating this, the category of morphisms in such a category naturally acquires a nontrivial filtration in the *objects*.
Working out all of category theory in this context is a big undertaking, which will probably not get done until people derive more actual utility from it. However, as a sort of test case to explore this system, I've spent some time thinking about how colimits should be defined, which I hope to explore in a future post.
[^1]: A metric without the requirement that d(f,g) = 0 implies f=g
Fragmentary-coarse groups are categorically neat [20220325115704-frag-coarse-spaces-have-a-nice-group-theory]
Fragmentary-coarse groups are categorically neat [20220325115704-frag-coarse-spaces-have-a-nice-group-theory]
Links 2022-01-26 [links-2022-01-26]
Links 2022-01-26 [links-2022-01-26]
Links 2022-01-22 [links-2022-01-22]
Links 2022-01-22 [links-2022-01-22]
- Dordle, a Wordle variant where you have to guess two words at the same time.
- Intercats, a new seminar from the Topos Institute on "categorical interaction". I'm scheduled to speak here (in June, so don't get too excited yet)
- How To Become A Magician. See also Becoming A Magician.
- Postmortem on RatVac. I have the highest level of respect for everyone who made their own vaccine - major props.
- Compositional Thermostatics from Baez, Lynch, and Moeller. I can also recommend Owen's blog.
Smooth dynamical systems as infinitesimal discrete dynamical systems [smooth-dynamical-systems-as-infinitesimal]
Smooth dynamical systems as infinitesimal discrete dynamical systems [smooth-dynamical-systems-as-infinitesimal]
Here I am working with nonstandard analysis in the sense of Robinson, taking an ultrapower of the real numbers and building things out of that. But in general I am going to be a bit sloppy and not worry too much about the details.
Recall that a standard function is _differentiable_ if, for every standard x and for every infinitesimal \epsilon , f(x+\epsilon )-f(x)/\epsilon \approx a, where a is also standard.
Fix an infinitesimal h. Let M be a standard differentiable manifold, fix p \in M, and consider the tangent space T_pM. Recall that the elements of this vector space (may be taken to be) smooth paths \gamma : I \to M, with 0 \in I \subset \mathbb {R} some open interval, up to the equivalence relation of having the same first derivative at p (which may be checked in any choice of local coordinates, all coordinates giving the same answer). In particular we may compute this derivative, letting \phi : U \to \mathbb {R}, p \in U \subset M being the local coordinates of choice, as the standard part of (\phi (\gamma (h))-\phi (p))/h. Having fixed h, we may thus replace each curve with just the choice of \gamma (h), the only condition on this being that in any choice of local coordinates, the above quotient has a standard part (eg it is not unbounded). But since the change-of-coordinate maps are in particular differentiable, it suffices to verify this for one such choice. We may call this property "being at O(h)-order infinitesimal distance from from p". For example, suppose that M = \mathbb {R}, p=0 and \phi = 1_\mathbb {R}. Then if h = (1/n), it will not do to take \gamma (h) = (1/\sqrt {n}), for in that case we will get the unbounded nonstandard real (\sqrt {n}) for the difference quotient.
Let \widetilde {D_pM} be the set of such points in M. We don't quite have a map T_pM \to \widetilde {D_pM}, because e.g the path \gamma (t)=t^2, which has local derivative zero, has \gamma (h) = h^2 \neq 0. In order to make this map well-defined, we need to consider a quotient by the relation of "being at distance o(h)". More precisely, let v \approx v' if, if any coordiante chart, d(v,v')/h is infinitesimal. (The local differentiability ensures this does not depend on the choice of coordinates.) Then let D_pM = \widetilde {D_pM}/\approx - now the map T_pM \to D_pM is well-defined.
We can also define a vector space structure on D_pM that makes this map linear. We simply lift the addition and scalar multiplication from any coordinate chart. Local differentiability imply that \psi (h(v+v')) = \psi '(0) h(v+v') + h\epsilon , wher \psi is a change-of-coordinate map, so that addition is well-defined up to an infinitesimal times h, which is quotiented out by in any case. Scalar multiplication works similarly. Note that we are defining a vector space over \mathbb {R}, _not_ over the full *\mathbb {R}. Multiplication by a number of order o(h) is not invertible (in fact such products are always zero), and similarly scaling by an unbounded number may take you out of the coordinate patch, and is thus not well-defined.
In fact with this, we have an isomorphism T_pM \to D_pM - any v \in D_pM is the image of \gamma (t) = p + tv/h, and two curves have the same derivative exactly if \gamma (h) \approx \gamma '(h).
Recall that smooth dynamical system on M is a smoth section M \to TM. We can exploit our isomorphism above, by observing that each D_p is actually a quotient of a subset of M. Hence we may ask for a function s: *M \to *M so that s(p) \in \widetilde {D_p} \subset *M - this induces a smooth dynamical system. Every (standard) smooth dynamical system has this form, and s,s' induce the same system if s(p) \approx s'(p) for each p.
What's cool about this is that these are essentially _discrete_ dynamical systems, albeit nonstandard ones. A discrete dynamical system is a set with an "advance one timestep" function s: X \to X. So a smooth dynamical system is a manifold with an "advance time h" function s: *M \to *M, subject to the condition that s(p) is h-close to p, and up to a certain equivalence relation. This suggests a way to use the same conceptual tools to study smooth and discrete dynamical systems.
The paper Differential geomtry via infinitesimal displacements, by Nowik and Katz, provides a more in-depth analysis of this idea.
Martin-Löf Random Sequences [20210618162423-martin_lof_random_sequences]
Martin-Löf Random Sequences [20210618162423-martin_lof_random_sequences]
A sequence of bits N \to \{0,1\} is _Martin-Löf random_ (or _algorithmically random_) if, roughly speaking, there is no _computable_ pattern to it.
There are three equivalent definitions:
Example of my reading process: Cellular sheaves of lattices and the Tarski laplacian [example-of-reading-process-cellular-sheaves]
Example of my reading process: Cellular sheaves of lattices and the Tarski laplacian [example-of-reading-process-cellular-sheaves]
There's a lot of sort of "implicit" skills that are important in various fields of science, that you really only learn by just hanging around older people that already know them and picking things up by osmosis. This is one of the things that make it hard to just learn things by reading textbooks, as opposed to actually going to a university and getting a degree. I think we should be doing more to study and teach these sorts of skills, to the extent that it may be possible.
Therefore, I've decided to write this post where I describe my "process" for reading papers by means of example. The paper I'll be reading is a random one that came across my feed[^fn:1]: Ghrist and Riess: Cellular Sheaves of Lattices and the Tarski Laplacian.
I got the idea for this project from Alexey Guzey tweeting this:
This post is an "async" version of Alexey's request - although as he notes in the replies to that tweet, the difference in learning rate between "reading what someone wrote about doing something" and "interacting with them as they do it live" is pretty insane. So this post is also an offer: if anyone wants to hop on a video call with me and hang out while I read a paper, let me know! My email is ayegill (at) gmail (dot) com.
Some notes before we begin:
- I selected this papre by skimming the abstract and deciding it looked interesting. Once I'd decided I would use this paper for this post, I committed to "finishing" reading it even if it turned out to be not that interesting - normally I might have skimmed it and decided not to keep reading it.
- "Finishing" is obviously still pretty variable - some papers I will read in a lot more detail than this one.
- My process involves a lot of being distracted by twitter, having to go do something else, and so on, which has been elided in this description.
This Week's Finds in ACT - April 25th [this-weeks-finds-in-act-20210425]
This Week's Finds in ACT - April 25th [this-weeks-finds-in-act-20210425]
I wrote a long post on one of the papers I read this week: Example of my reading process: Cellular sheaves of lattices and the Tarski laplacian. See that post for the details!
Some other stuff:
This Week's Finds in ACT [this-weeks-finds-in-act-20210418]
This Week's Finds in ACT [this-weeks-finds-in-act-20210418]
John Baez wrote a regular blog/column called "This Week's Finds in Mathematical Physics" circa 1993-2012. The entries are really a treasure trove of cool mathematical nuggets, covering everything from hardcore theoretical physics, group theory, climate models, category theory, and more.
Imitation being the sincerest form of flattery, I decided to shamelessly steal this format, and so this is hopefully the first of many "This Week's Finds in Applied Category Theory". Below, I've summarized a few of the papers/blog post/notes/whatever I read this week. I didn't stick religiously to things I first came across this week, and indeed some of these are pretty old, but they're all things I spent some time mulling over this week.
March 2021 Links [march-2021-links]
March 2021 Links [march-2021-links]
Also contains links from February.
Fantastic Anachronism: Two Paths to the Future
Ansuz: What color are your bits? What do the notions of "random number" and "copyrighted music" have in common? They're not about the specific bits under consideration, but about their _color_.
mike_hawke: Some random parenting ideas.
I was very taken with Lucy Greer's blog drossbucket in general, and I particularly enjoyed this recent post: Speedrun: "Sensemaking", where she tries find out as much as she can about this nebulous term in one hour. Seems like a cool thing to emulate!
Michael Nielsen: Maps of Matter.
Derek Sivers: There is no speed limit
Autotranslucence: Becoming a Magician
Higman's embedding theorem states that a finitely generated group can be embedded as a subgroup of a finitely presented group precisely if there is a presentation where the relations are recursively enumerable, i.e there is a computer program that generates them one after the other. Of course this statement makes sense if you replace "group" here by any single-sorted algebraic theory (i.e Lawvere theory) - The Boone Conjecture is the conjecture that it's always true. This is now known to be false in general, but of course the problem of characterizing those algebraic theories which have this property remains. I find this extremely cool because it reduces a question about computability theory - which seems to require a lot of essentially arbitrary choices about how powerful the model of computation should be, etc - to a purely algebraic question.
Why Python Is Better Than Haskell [why-python-is-better-than-haskell]
Why Python Is Better Than Haskell [why-python-is-better-than-haskell]
Also read Hillel Wayne: Why Python Is My Favorite Language.
So: I like python a lot. On the other hand, I also really like haskell. I like functional programming. I like putting information into types, and having the types checked at compile-time. I like higher-order function like `map`. By god, I even like monads. I think monadic parser-combinators are just about the coolest thing in the world - especially the fact that you can implement them as a library!
Python is very antithetical to that. It obviously doesn't have static types. It has higher-order functions, but their use isn't super idiomatic. It's not pure. But... I still really like coding in it. In a lot of cases I _strongly_ prefer writing Python to Haskell. Probably the strongest reason for that is the build situation in Haskell, which is extremely stupid. But actually even allowing that, python seems to have a certain ease of use that Haskell doesn't. Why is that? I think the key thing is that _Haskell makes it easy to create new abstractions and regards it as a normal part of coding_.
Wait, what? Weren't we talking about things that make _python_ easier to use? Yes. That's what I mean. The fact that Haskell makes it easy and expected to introduce new abstractions means that, to pick up a new library, I need to understand its abstractions, and probably massage an interface between them and my program. That's super annoying.
When writing in python, there are essentially no abstractions, beyond the bare minimum of procedural "each command modifies variables and does IO and returns a value", along with a very small set of types of data: numbers, strings, maps, lists. It's not that this makes libraries easy to integrate, it's that it makes them _easy to understand_. To use `requests` to talk to mailgun, here's what I did:
# the variables are populated further up... r = requests.post( mgurl, auth=("api",MAILGUN_APIKEY), data={"from": sender, "to": [TARGET_MAIL], "subject": subject, "text": text}) return(r.text)I want to make a post request with some arguments, and get a response back (actually the response doesn't matter that much in this application, but whatever). I build the arguments (strings) and the url (a string), then shove all this into `post` function.
Here's the top google result for "haskell make post request", which I just googled now while writing this post. Okay.. so I need to find a `RequestBody` (what's that?) and use `parseRequest` to turn my url into a request, where I can then insert my body..?
I go to the `http-conduit` docs, where I see this:
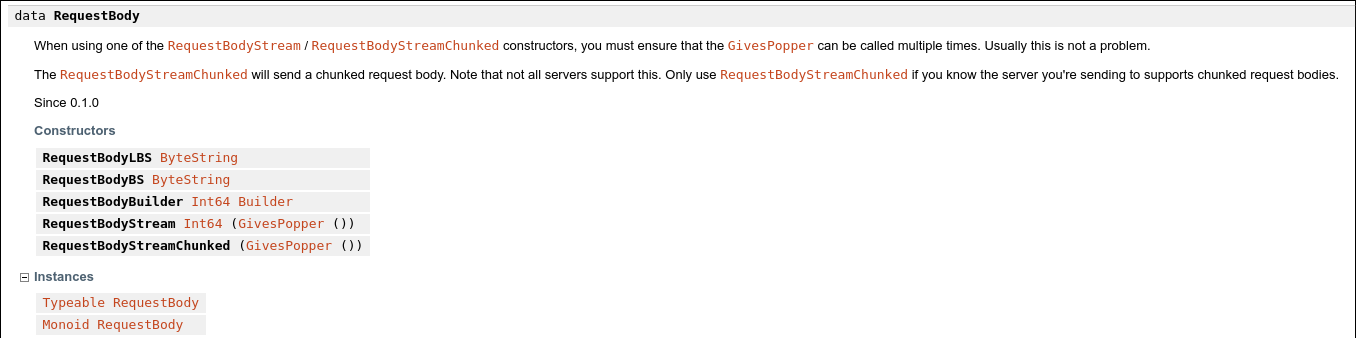
Okay, so after staring at this for a bit, it seems like you just put in a bytestring? That's _slightly_ more low-level than I was hoping - to be honest, I don't even know how to format a list of arguments like the above into a http request!
After digging around the docs page for a little while, I find this:
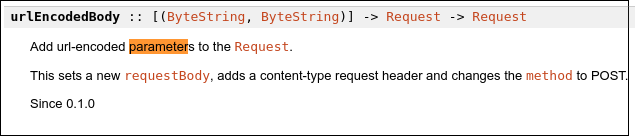
Okay.. that doesn't look too bad. Now we can implement the fragment above in Haskell like this:
do manager <- newManager defaultManagerSettings request <- urlEncodeBody [("from", sender),("to",targetMail),("subject",subject),("text",text)] <$> parseRequest mgurl response <- httpLbs request manager return $ body response(I actually haven't checked whether this works like I expect it to, so don't be shocked if this code doesn't work as written).
Okay, so in this _very simple_ case, we needed to understand two new types: `Manager` and `Request`. `RequestBody` turned out to be a red herring, although I also looked that one up. I'm going to allow `ByteString` as part of the "standard library", but if I was really writing this code I probably would've had to look up/remember how to convert between string types.
The `Manager` object keeps track of open connections, which is probably not needed for my application. Do I need to close my connections after I'm done or something? I actually make some other http requests earlier in this application - does it matter if I use the same manager?
Why does `parseRequest` use the `IO` monad? (Looks at the docs) okay, it actually uses `MonadThrow`, so I guess I should make a decision about how to handle a parse error - should I just crash with an exception or handle the error more gracefully (the Python version of this script has logging - that's probably what "should" be done).
Is this all very complicated? No. Is it bad design? Also no. `http-conduit` provides stuff like `simpleHttp :: MonadIO m => String -> m ByteString` which lets you do simple requests. I'm gonna assume giving people the option of passing a manager object around is a good idea. Making people be explicit about what request they want instead of just making a best guess based on the arguments passed to `requests.post`.
Once your application gets more complicated, the extra structure imposed by Haskell starts paying dividends - the abstractions begin to simplify things, justifying the upfront cost of understanding them. And the abstractions built by the _user_ - not imported from libraries but custom-built for this application - start becoming worthwhile.
But while you're still at the "fucking around to do something simple" stage, it's all very overkill.
January 2021 Links [january-2021-links]
January 2021 Links [january-2021-links]
Alvaro de Menard: Are Experts Real?, and the followup, Unjustified True Disbelief. The former:
> There's a superficial uniformity in the academy. If you visit the physics department and the psychology department of a university they will appear very similar: the people working there have the same titles, they instruct students in the same degrees, and publish similar-looking papers in similar-looking journals.6 The N=59 crew display the exact same shibboleths as the real scientists. This similarity provides cover so that hacks can attain the prestige, without the competence, of academic credentials. > Despite vastly different levels of rigor, different fields are treated with the ~same seriousness. Electrical engineering is definitely real, and the government bases all sorts of policies on the knowledge of electrical engineers. On the other hand nutrition is pretty much completely fake, yet the government dutifully informs you that you should eat tons of cereal and a couple loaves of bread every day. A USDA bureaucrat can hardly override the Scientists (and really, would you want them to?).
Concavenator: Gods of Salt.
Michael Shulman: The Logic of Space. Especially recommend section 2.1, "On Syntax." See also this discussion of a related point on twitter. "How much information is actually in a universal property" is a fascinating question, one I actually might write a longer post about at some point.
Sarah Constantin: Wrongology 101. Unfortunately seems to suffer from a spot of bad formatting.
Escardó-Simpson: A universal characterization of the closed Euclidean interval. People often say stuff like "analysis is coalgebraic" - the description of the unit interval in this paper in what is essentially finitary terms is probably the purest example I've seen of this.
Interesting thread: Joel David Hamkins On Twitter
Nintil: Longevity FAQ.
SSC IS BACK BABY, now called "Astral Codex Ten". I also recommend going to the website of Scott's new psychiatry practice, Lorien Psychiatry, and reading his writing on psych, especially Ontology of Psychiatric Conditions: Taxometrics. I enjoyed Contra Weyl on Technocracy, but found it a bit weak (I especially feel the "technocracy success stories" weren't very strong). I think this is because both Scott and Weyl are using the term Technocracy in a sort of confused way, although Scott seems to be grappling towards understanding in this post. I think this is an object-level disagreement masquerading as a meta-level disagreement (which is also why all of Weyls actual alternative policy proposals smell so much like more technocracy - technocracy isn't really describing what it is he's against.) I really liked this quote:
> There is no way to perfectly calculate the devastation of a potential pandemic that hasn't happened yet. But once you make even a weak effort, you notice that all the numbers are really really big.
Jeff Kaufman: Bets, Bonds and Kindergarten. I might steal this idea for when I have my own children.
Alice Maz: Alien Intelligences
Philip Wadler: Theorems for free!
Junk Heap Homotopy: The Four Intuitions. (Physical, Computational, Algebraic, Geometric).
Milan Cvitcovic: Things You're Allowed To Do. Put it on Tab Snooze and read it every month.
Notes from "Practical Foundations for Programming Languages [notes-from-pfpl]
Notes from "Practical Foundations for Programming Languages [notes-from-pfpl]
_Practical Foundations for Programming Languages_ (PFPL), by Robert Harper, is an introduction to the theory of programming languages. I recently finished reading through it. My read was fairly cursory - I stopped to think about ideas which seemed important or interesting, but I didn't read everything deeply, and I didn't do a lot of exercises.
In this post I'll summarize the things I got from it that seemed really interesting. I'll be giving my own perspective (much more category-oritented), not trying to stick to the book. This also means I might be mixing in some of my own thoughts that weren't really in the text, without any effort made to distinguish them. Sorry! If there's a dumb thing here don't assume that means the book is dumb.
Where numbers come from [numbers]
Where numbers come from [numbers]
Alternative title: Wolves hate him!! Shepherd compares the size of large sets with this one easy trick!
Previously: Recognizing Numbers
Let's do a thought experiment. I place an empty box in front of you. Then, while you're watching, I put these objects into the box:
Then I remove these things from the box:
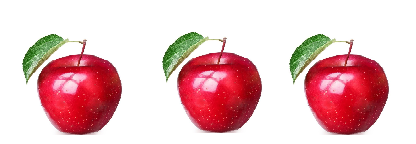
You're surprised! Why? Because what I took out is not a subset of what I put in. A new apple appeared.
You can do this experiment with animals, and small children of various ages, and monitor them carefully to see if they seem surprised. You can also try *larger collections of apples*, to see how large a collection of apples they can keep track of.
Once children are old enough to talk, you can make the experiment more reliable by simply asking them if the box is empty. But of course, there's a small window of interestingness here - children beyond a certain age rapidly get extremely good at this problem, and from a certain point humans basically never fail at this task, unless the pile of apples gets extremely large. This does not surprise you at all.
The following picture switches back and forth between two collections of apples. Can you tell whether they're the same size "in one go" - without letting it switch back and forth more than once?
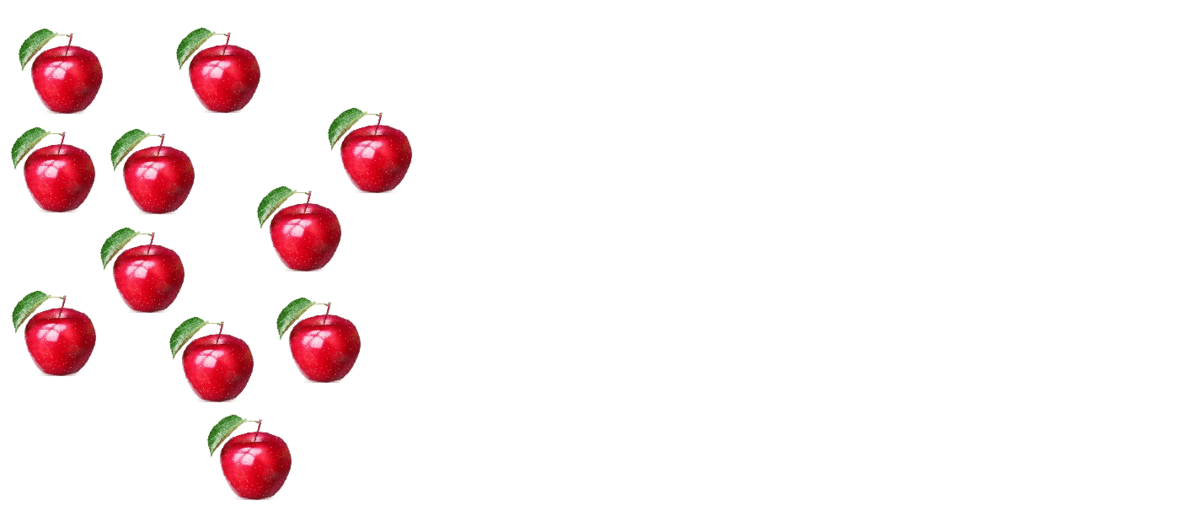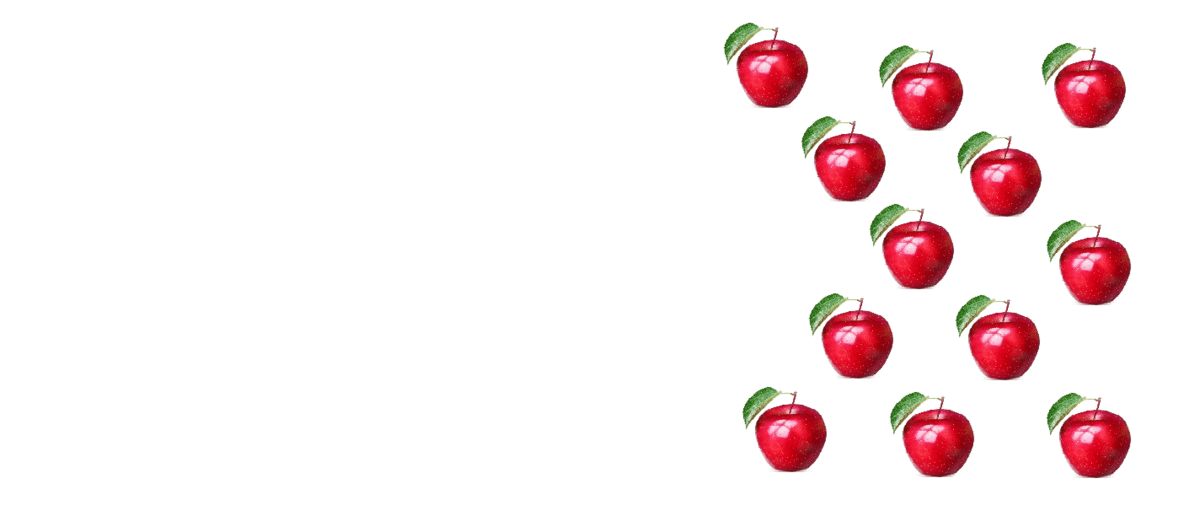
This, it turns out, is actually very hard. Even grown human brains don't come hardwired with an arbitrarily powerful "compare the size of two collections" module. You can compare the *visual* size, which can give you the answer if the relative difference in size is moderately large. But in a case like the above, it's very hard to tell the size of those two collections apart.
Here's a simple piece of technology for comparing the size of two collections: pair of the elements one after the other. If the collections are exhausted at the same time, they're the same size. If not, whichever has elements left at the end is bigger.
Of course, this won't work if the collections are not available *at the same time* to be compared. This could be for a contrived reason like above, the image flashing back and forth. Or it could be for a practical reason - a shepherd wants to compare the set of sheep in the pen when he opens the gate in the morning to the set of sheep in the pen before he closes the gate at night.
So humans, so long ago that the origins have been completely forgotten, but certainly more than 20.000 years ago, came up with an ingenious technology to solve this problem:

I will describe it for you now. We invented a *reference set* of every possible size (infinities had not been invented yet). There are many such families of reference sets, but here is the one you are probably familiar with:
- \{1\}
- \{1,2\}
- \{1,2,3\}
- \dots
Before I let out the sheep in the morning, I *identify the reference set with the same size as the collection of sheep*. I do this by the procedure used above - I match up sheep with elements of the reference sets until I run out of sheep. "1,2,3,4,5,6,7,8,9,10,11". Now I know that the collection of sheep has the same size as the collection \{1,2,3,4,5,6,7,8,9,10,11\}. This is called *counting*. In the evening, I compare that collection with the collection of sheep that came back - if they're not the same size, I know about the discrepancy.
It's important to emphasize that numbers are really a *technology* - it had to be invented. We know this because there exist communities without this technology. You've probably heard about languages without a name for numbers above 2 - "one, two, many". Well, that's more or less real. The most famous are the Pirahã of the Amazon rainforest. Their language has two words "hói" "hoí" (distinguished by tone) - originally taken to mean "one" and "two", but now believed to probably mean something like "small quantity" and "larger quantity". These are the closest thing to numerals in their language. Experiments like the one I described at the beginning have been put to them[^2] - even adult humans usually begin to fail at this task even when the number of objects is as low as four or five. They *don't* fail at this task when simply asked to match the number of object placed in a line of the table. They understand what it means for two sets to be *in bijection*, but they lack the technology of numbers to keep track of this information. The Pirahã are quite capable of hunting, gathering, cultivating manioc, crafting bows and arrows, building huts, and generally surviving in the jungle. They're not *stupid*. But they really, truly, do not know how to count.[^3]
[^3]: Actually, it seems some meddlesome people have started teaching the Pirahã Portugese, including numerals, and basic mathematics. So the world may be about to lose one of the few examples of numberless peoplmay be about to lose one of the few examples of numberless people..
The main trick here is *abstraction*. We remove all the details of the individual sheep and remember *only* the "number" - the *size* of the collection, its ability to count other things, be in bijection with other things. A mathematician might say "the bijection class of the set", if they did not have the word "number".
The second trick, also important, is *reification*. You can see how much I fumble for words above, trying to describe the concept "the number of elements in a set" without using the word "number". This is not a quantity you can put inside your brain. So we choose a *simple representative*. Whoever made the Ishango bone, pictured above, choose a set of marks on a bone to represent the bijection class. This is convenient because you can just keep the set of marks, i.e the bone, with you until you need the number again (unlike the set of sheep, which you have to let out to graze, that's the whole point). Another implementation is by creating a set of *words*. The set \{1,2,3\}, or \{\text {one}, \text {two}, \text {three}\}, is a handy set of a given size. We name this set after its largest element - "three" - and to reconstruct the set from the name, you only need to recall the order of the special size-words[^1]
[^1]: In mathematics, we might define 3 to be the set \{0,1,2\} instead - this has the advantage that the definition is not self-referential, and maybe technically convenient for other reasons. But most people count starting from 1, not 0.
[^2]: See Number as a cognitive technology: Evidence from Pirahã language and cognition. Concretely, the subjects were asked to match the number of objects placed by the experimenter. In one experiment, the experimenter simply put objects down in a line on the table. In another, the objects were dropped one after the other into an opaque container. The subject then had to place the same number of objects on their side of the table. There were a few different versions of this. Maybe it's important to note here that this study was not exactly high-n, and communication with the subjects was unreliable for obvious reasons. There were a few failures even on the "easy" versions of the tasks, so perhaps it's not entirely clear how much of the results should be put down to the subjects having trouble representing cardinalities in their head, and how much should be put down to different versions of the task being harder to understand, or even simply deciding to mess with the experimenters.
(Thanks to John for inspiring me to write this).
December 2020 Links [december-2020-links]
December 2020 Links [december-2020-links]
A list of some of the things I found interesting in December.
Low-Tech Magazine: "Low-tech Magazine questions the blind belief in technological progress, and talks about the potential of past and often forgotten knowledge and technologies when it comes to designing a sustainable society. Interesting possibilities arise when you combine old technology with new knowledge and new materials, or when you apply old concepts and traditional knowledge to modern technology". Sample articles: The Curse of the Modern Office, Well-tended fires outperform modern cooking stoves, Why we need a speed limit for the internet.
Evangelia Aleiferi: Cartesian Double Categories with an Emphasis on Characterizing Spans.
Owen Lynch: Haskell's Children (Owen's whole blog is worth reading).
Tobias Fritz has put up some slides discussing our new preprint about comparison of experiments (with Paolo Perrone and Tomás Gonda).
I've been rereading Bayesian Updates Compose Optically by Toby St Clere Smithe.
Michael Nielsen: Principles of Effective Research.
Applied Divinity Studies: Isolated Demands for Rigor in New Optimism. "More likely, solar power has been making great strides on a pretty consistent basis for decades, and the only recent break is in how high-status it is to say that out loud."
Jules Hedges: Compositional Game Theory Reading List
Jason Collins: Principles for the application of Human Intelligence
George on LessWrong: Machine Learning May Be Fundamentally Unexplainable. "When we say that we “understand” physics what we really mean is that there are a few dozen of thousands of blokes that spent half their lives turning their brains into hyper-optimized physics-thinking machines and they assure us that they “understand” it."
Amanda Askell: In AI Ethics, "Bad" Isn't Good Enough.
A map of properties of logical theories: <https://forkinganddividing.com/>
Galois Connections and Nullstellensatzen [galois-connections-and-nullstellensatzen]
Galois Connections and Nullstellensatzen [galois-connections-and-nullstellensatzen]
(The idea for this post is due to this tweet by @sarah_zrf)
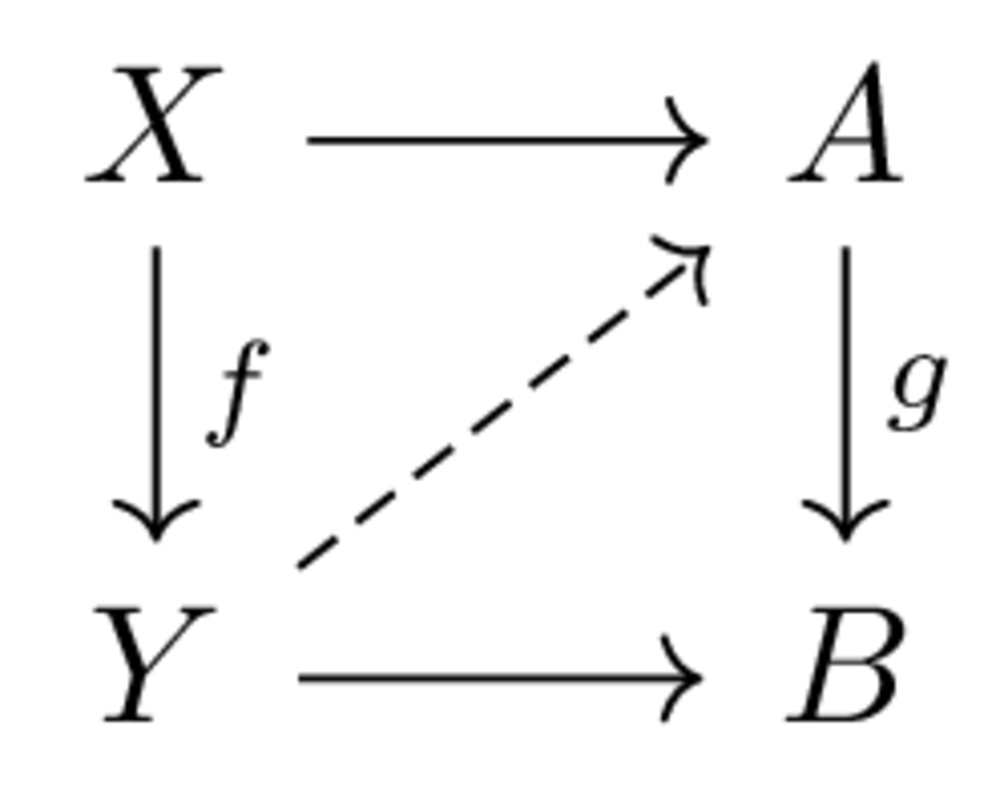
Demystifying the second law of thermodynamics [demystifying-the-second-law-of-thermodynamics]
Demystifying the second law of thermodynamics [demystifying-the-second-law-of-thermodynamics]
Thermodynamics is really weird. Most people have probably encountered a bad explanation of the basics at some point in school, but probably don't remember more than
- Energy is conserved
- Entropy increases
- There's something called the ideal gas law/ideal gas equation.
Energy conservation is not very mysterious. Apart from some weirdness around defining energy in general, it's just a thing you can prove from whatever laws of motion you're using.
But _entropy_ is very weird. You've heard that it measures "disorder" in some vague sense. Maybe you've heard that it's connected to the Shannon entropy of a probability distribution H(p) = \sum _x - p(x)\ln p(x). Probably the weirdest thing about it is the law it obeys: It's not conserved, but rather it _increases_ with time. This is more or less the only law like that in physics.
It gets even weirder when you consider that at least classical Newtonian physics is _time-symmetric_. Roughly speaking, this means if you have a movie of things interacting under the laws of Newton, and you play it backwards, they're still obeying the laws of Newton. An orbiting moon just looks like it's orbiting in the other direction, which is perfectly consistent. A stone which is falling towards earth and accelerating looks like it's flying away from earth and decelerating - exactly as gravity is supposed to do.
But if there's some "entropy" quality out there that only increases, then that's obviously impossible! When you played the movie backwards, you'd be able to tell that entropy was decreasing, and if entropy always increases, some law is being violated. So what, is entropy some artefact of quantum mechanics? No, as it turns out. Entropy is an artefact of the fact that you can't measure all the particles in the universe at once. And the fact that it seems to always increase is a consequence of the fact that matter is stable at large scales.
The points in this post are largely from E.T. Jaynes' Macroscopic Prediction.
A response to Maudlin on credence and chance [a-response-to-maudlin-on-credence-and-chance]
A response to Maudlin on credence and chance [a-response-to-maudlin-on-credence-and-chance]
Credence - and chance - without numbers (and with the Euclidean property) is a philosophy paper by Tim Maudlin. In it, Maudlin discusses the closely related notions of _credence_, the subjective likelyhood that a specific agent associates to some outcome, and _chance_, the objective likelyhood that the event happens. He argues that
- The traditional approach of measuring these outcomes with numbers is wrong, but
- this shouldn't trouble us too much, because we can do a lot without them.
As it happens, I have my own serious reservations about the traditional measure-theoretic formulation of probability (due to Kolmogoro). By I still think this paper is more or less terrible. Maudlin displays a Wikipedia-level understanding of the paradoxes surrounding infinity in probability theory. His proposed solution amounts to enumerating a list of properties that an agent's system of credence should satisfy, and arguing that these axioms suffice for the things we usually want to do with "subjective degree of belief". This is actually fine such as it is, but his description of this is also seriously lacking.
reMarkable 2 review [remarkable-2-review]
reMarkable 2 review [remarkable-2-review]
I recently got a reMarkable 2. I've had it for one week. This is my review of it so far.
Euler's method is compositional [eulers-method-is-compositional]
Euler's method is compositional [eulers-method-is-compositional]
Another day, another post about dynamical systems. Today, I want to think about _open_ dynamical systems. You can think of an open dynamical system as a system where
- The dynamics are parameterized by some variable (which is supposed to vary with time)
- And some function of the state is exposed (maybe to parameterize other systems).
I want to describe two types of open dynamical systems: continuous ones and discrete ones, and show that Euler's method is a compositional mapping between them.
Cofree dynamical systems and chaos [cofree-dynamical-systems-and-chaos]
Cofree dynamical systems and chaos [cofree-dynamical-systems-and-chaos]
This blog post largely retraces ideas from Lawvere: Functorial remarks on the general concept of chaos. I saw this in this tweet from Jade Master, which this blog post is basically an extended version of. Hat tip to her.
Let's try to apply category theory to the study of "dynamical systems". What is a dynamical system? There are a lot of different versions:
- A discrete dynamical system is a set S with a map S \to S.
- A discrete Markov process if a countable set S equipped with a stochastic S\times S matrix.
- A smooth dynamical systsem is a smooth manifold M equipped with a section of the tangent bundle M \to TM.
Today, we'll take the following general view:
Let \mathcal {C} be a symmetric monoidal category, and let (T,+,0) be a commutative monoid in \mathcal {C}[^fn:1]. Then a T-dynamical system is simply an object S of \mathcal {C} equipped with an action of T, T \otimes S \to S.
We think of the elements of T as "time-shifts", and the composition adds these together. Using this, we can recover a wide variety of different types of dynamical systems:
- Let \mathcal {C} be the category of sets, equipped with the cartesian monoidal structure. Let T = \mathbb {N}_0. Then a \mathbb {N}_0-dynamical system is exactly a discrete dynamical system in the previous sense.
- Let instead \mathcal {C} = \aleph _0\operatorname {-}\mathsf {Stoch} be the category of countable sets and Markov kernels, and let T be \mathbb {N}_0 again (with the usual monoidal structure regarded as a deterministic Markov kernel). Then a \mathbb {N}_0-dynamical system is exactly a discrete Markov process[^fn:2]
- Let \mathcal {C} be the category of smooth manifolds with the Cartesian monoidal structure, and let T = \mathbb {R}. Then an \mathbb {R}-dynamical system is _almost_ the same thing as a smooth dynamical system in the above sense. A \mathbb {R}-dynamical system picks out a smooth trajectory f(-,m) : \mathbb {R} \to M for each m \in M, in a compatible way. This gives a smooth vector field (i.e a smooth dynamical system in the above sense) m \mapsto f'(0,m).
This is not quite a 1-1 correspondence, for example because even smooth dynamical systems in that sense can experience "finite-time-blowup". For example, if we let M = \mathbb {R}, then this a dynamical system is just an ordinary (time-independent) differential equation. If we put f'(t) = f(t)^2, the unique solution given f(0) = y_0 is \frac {1}{y_0^{-1}-x}, which goes to \infty as x \to y_0^{-1}. So there is no way to find a trajectory, extended for arbitrarily long time, which solves this equation. But on the other hand, perhaps equations like this are bad and shouldn't be counted. Anyways, they are not dynamical systems in this sense.
Let Dyn(T) denote the category of T-dynamical systems - their maps are simply T-equivariant maps. There is an obvious forgetful functor Dyn(T) \to \mathcal {C}.
Suppose \mathcal {C} is a closed monoidal category. Then the above functor has a right adjoint, which sends M to [T,M]. T acts on [T,M] simply by "translation", i.e (t.f)(t') = f(t+t') To be more formal, the map T\otimes [T,M] \to [T,M] is adjoint to the map T \otimes [T,M] \otimes T \to M given by multiplying the 2 Ts, then evaluating the hom.
Proof: We claim that Hom_{Dyn(T)}([M,[T,M']]) \cong Hom_\mathcal {C}(M,M').
Suppose we have a T-equivariant map \phi : M \to [T,M']. T-equivariance, of course, means that the diagram
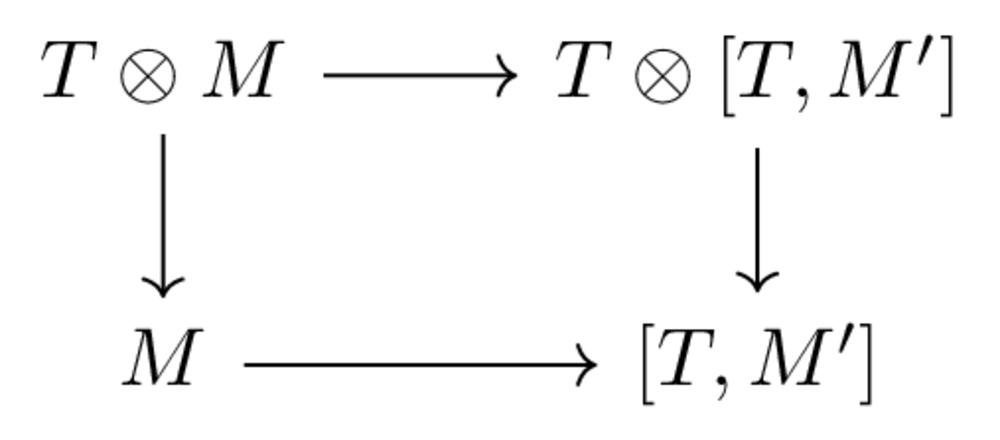
commutes.
The bare map M \to [T,M'] corresponds to a map M \otimes T \to M'. The above commutative square means that this square commutes:
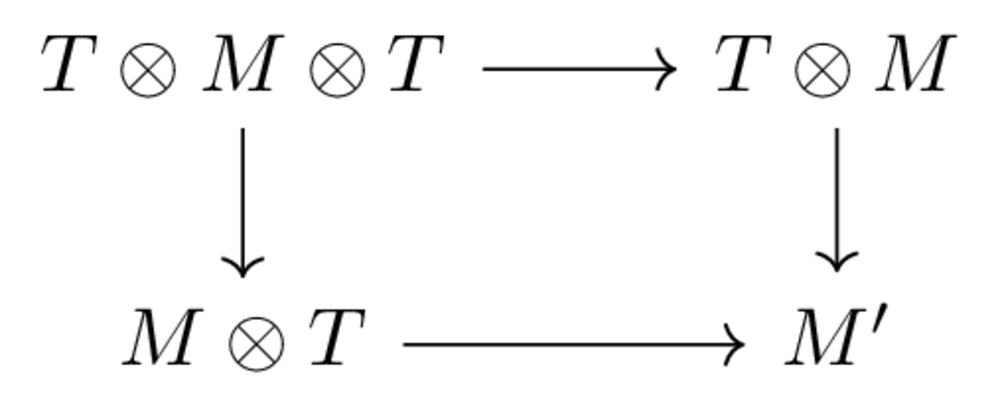
The bottom way around is "let T act on M, then use the map". The other one is "multiply the Ts together, then use the map".
Now let's insert the unit into the right-hand T:
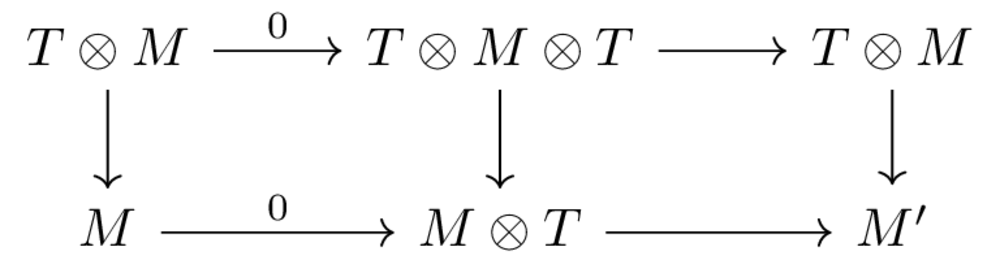
Both these squares commute. And the top arrow is just the identity. In other words the classifying map T \otimes M \to M' must equal the other composite, which is "act, and evaluate at 0". Equationally, if f: M \to [T,M'], this means f(m)(t) = f(t.m)(0). This means the map f:M \to [T,M'] is uniquely determined by the map M \to M' given by evaluation at 0. On the other hand, it's not hard to see that any map M \to M' can be extended to an equivariant map by this method. This concludes the proof.
Now, what can we do with these "cofree dynamical systems"[^fn:3]? Here is a cool thing: We can give a categorical definition of _chaos_.
Let M be a T-dynamical system. Let o:M \to X be a map in \mathcal {C} on the underlying space of M. We can think of o as an "observable": some property of the state which we can measure. There is a corresponding map of systems M \to [T,X] which takes each point in M to its trajectory of observations We say M is _chaotic_ with respect to o if map M \to [T,X] is an epimorphism.
If we think of an epimorphism as a "surjection", this means every possible sequence of observations is possible. In other words, our current observations don't exclude any possible pattern of future observations.
[^fn:1]: It is not really important that these are symmetric and commutative, but I can't be bothered to keep track of the order, and I don't have any natural non-commutative examples [^fn:2]: It may have been more natural to consider finite-state Markov processes, but of course \mathbb {N}_0 isn't finite, so that wouldn't quite have worked [^fn:3]: Incidentally, there is also a further left adjoint, the "free dynamical system", given by M \mapsto T \otimes M
Chu spaces and linear logic [chu-spaces-and-linear-logic]
Chu spaces and linear logic [chu-spaces-and-linear-logic]
A _Chu space over S_ consists of a pair of sets (X,U), and a function e: X \times U \to S. A map of chu spaces (X,U,e) \to (Y,V,e') is a pair of maps X \to Y, V \to U so that the diagram
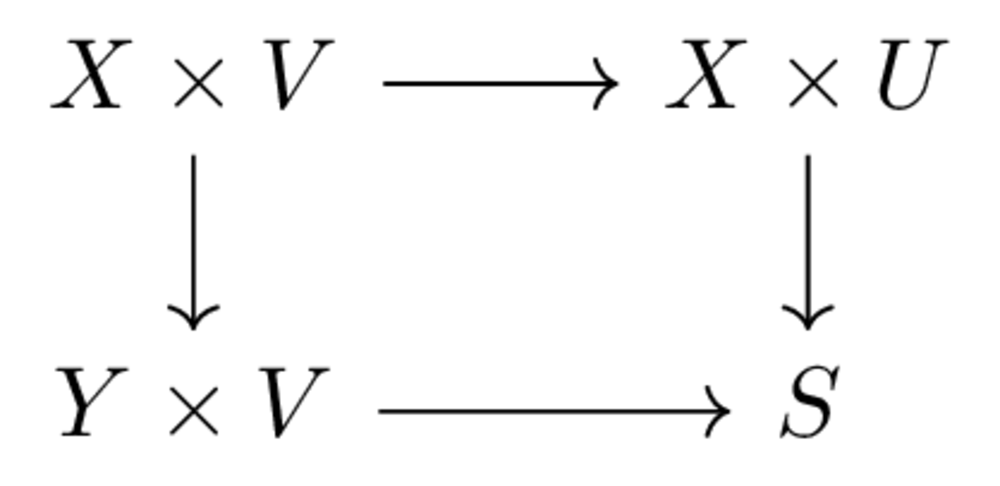
commutes. This defines a category of Chu spaces, called Chu(Set,S) You can think of a Chu space as a normal-form game. X is the set of choices available to one player, and U is the set of choices available to the other. The outcome, given the choices x and u, is e(x,u).
You can think of a map of Chu spaces as a way of transforming strategies between the two games. If you would play x \in X in the original game, you instead play f(x) \in Y. The map in the opposite direction ensures that, no matter what your opponent chooses in the target game, the same outcome could have happened in the domain game - hence your strategy is no worse, in some vague sense (but note that there is no ordering on S, so this does not literally make sense).
The cool thing is that Chu spaces are also a model of linear logic, in a way that sort of reflects "Game semantics for linear logic", but with some important differences (which we will see).
Game semantics of linear logic [game-semantics-of-linear-logic]
Game semantics of linear logic [game-semantics-of-linear-logic]
Linear logic is a weird sort of logic. It's most commonly explained by saying that the "weakening" rule: <object type="image/svg+xml" data="/ox-hugo/20200414104653-blog_posts_570c4c92abfcb8419f3d26233037e0de1c74aecf.svg" class="org-svg"> Sorry, your browser does not support SVG.</object> and the "contraction" rule <object type="image/svg+xml" data="/ox-hugo/20200414104653-blog_posts_b3da13021d306636a1a258e2de559738f5f41da8.svg" class="org-svg"> Sorry, your browser does not support SVG.</object>. In other words - you have to use all the assumptions, and you can't use an assumption more than once. This is usually interpreted in terms of _resources_ - just because I can make a <object type="image/svg+xml" data="/ox-hugo/20200414104653-blog_posts_8582cbf09790ec5906444f9f5df9cd00053cb98e.svg" class="org-svg"> Sorry, your browser does not support SVG.</object> out of two As doesn't mean I can do it with one <object type="image/svg+xml" data="/ox-hugo/20200414104653-blog_posts_a7d92cc965ef976b84b9370a6f429d98bc7d2fb9.svg" class="org-svg"> Sorry, your browser does not support SVG.</object>. And I can't just throw an <object type="image/svg+xml" data="/ox-hugo/20200414104653-blog_posts_a7d92cc965ef976b84b9370a6f429d98bc7d2fb9.svg" class="org-svg"> Sorry, your browser does not support SVG.</object> away that I might not need - I need to find a process for getting rid of it.
However, there's also another way of thinking about linear logics - in terms of _games_. The combinators of linear logics become ways of combining games into other games. The interpretation of the deduction rules is now that a proof of the sequent <object type="image/svg+xml" data="/ox-hugo/20200414104653-blog_posts_fbc8e225dbcfabfee571f016d25f90b9b3aca8af.svg" class="org-svg"> Sorry, your browser does not support SVG.</object> should provide a winning strategy for <object type="image/svg+xml" data="/ox-hugo/20200414104653-blog_posts_a7d92cc965ef976b84b9370a6f429d98bc7d2fb9.svg" class="org-svg"> Sorry, your browser does not support SVG.</object>.
Let us be a bit more (but not too) precise. There are two players. Following convention, we call them the _prover_, P, and the _opponent_, O. It is understood that we are "on the side" of P, although we could equally well do it the other way - the logic is symmetric enough for that. A game has a starting player (in many treatments, it is assumed the opponent always goes first, but not here). Play is usually assumed to proceed back and forth, each player making one move at a time, but this is not important - the most important thing is that in each position, there is a well-defined next player. Each player has a number of possible moves, only some of which may be legal in a given position - by "position", we simply mean the sequence of moves so far. We generally think of a player as losing when they have to move, but have no legal moves.
The most basic operator is the "dual" or "negation" operator, <object type="image/svg+xml" data="/ox-hugo/20200414104653-blog_posts_bc4947b04e7ea496037197a0809d11da55422409.svg" class="org-svg"> Sorry, your browser does not support SVG.</object>. This simply interchanges the position of the players. The next operator is <object type="image/svg+xml" data="/ox-hugo/20200414104653-blog_posts_279df3c8f4a8f9a7e4ae8fbdb05c6f1d880f9c99.svg" class="org-svg"> Sorry, your browser does not support SVG.</object>. This game consist of playing <object type="image/svg+xml" data="/ox-hugo/20200414104653-blog_posts_a7d92cc965ef976b84b9370a6f429d98bc7d2fb9.svg" class="org-svg"> Sorry, your browser does not support SVG.</object> and <object type="image/svg+xml" data="/ox-hugo/20200414104653-blog_posts_8582cbf09790ec5906444f9f5df9cd00053cb98e.svg" class="org-svg"> Sorry, your browser does not support SVG.</object> simultaneously - the player must move in whatever game the opponent just moved in, while the opponent can switch games at will.
Clearly, a winning strategy for this game, for the player, entails a winning strategy for each component game. In this sense, this game is like logical "and".
But there's also another operator like "and", which is written <object type="image/svg+xml" data="/ox-hugo/20200414104653-blog_posts_cd339c6a9fd60f255d5641e7b67849d12862ec66.svg" class="org-svg"> Sorry, your browser does not support SVG.</object>. This is played as follows: the opponent chooses a game, then that game is played to completion, and its winner wins the whole game.
Here is a difference between these operators: There is a canonical strategy for <object type="image/svg+xml" data="/ox-hugo/20200414104653-blog_posts_c224d906e554f6971f4d8beea3fbf24f53936870.svg" class="org-svg"> Sorry, your browser does not support SVG.</object>, but not for <object type="image/svg+xml" data="/ox-hugo/20200414104653-blog_posts_c7ea9bf60399dae5f34e826d4f1a8ecc0a4a6030.svg" class="org-svg"> Sorry, your browser does not support SVG.</object>. How does this work? To play <object type="image/svg+xml" data="/ox-hugo/20200414104653-blog_posts_c224d906e554f6971f4d8beea3fbf24f53936870.svg" class="org-svg"> Sorry, your browser does not support SVG.</object>, we must play the opponent's side in <object type="image/svg+xml" data="/ox-hugo/20200414104653-blog_posts_d3860e22107b32eb22a9449fa3807d8f08cea676.svg" class="org-svg"> Sorry, your browser does not support SVG.</object>. Assume wlog that the player goes first in <object type="image/svg+xml" data="/ox-hugo/20200414104653-blog_posts_a7d92cc965ef976b84b9370a6f429d98bc7d2fb9.svg" class="org-svg"> Sorry, your browser does not support SVG.</object>. We have the player start playing in <object type="image/svg+xml" data="/ox-hugo/20200414104653-blog_posts_a7d92cc965ef976b84b9370a6f429d98bc7d2fb9.svg" class="org-svg"> Sorry, your browser does not support SVG.</object>, then copy this move into <object type="image/svg+xml" data="/ox-hugo/20200414104653-blog_posts_bc4947b04e7ea496037197a0809d11da55422409.svg" class="org-svg"> Sorry, your browser does not support SVG.</object>. Whatever they play in response, we go to <object type="image/svg+xml" data="/ox-hugo/20200414104653-blog_posts_a7d92cc965ef976b84b9370a6f429d98bc7d2fb9.svg" class="org-svg"> Sorry, your browser does not support SVG.</object> and play that as our response to them, and so on. We're guaranteed to win (exactly) one of the games, since the two games will be exactly mirrored. If this doesn't make sense, imagine playing two chess games against another person - one as black, one as white. Starting with the game in which they're white, they make a move. You copy this move on the other chessboard. They respond with black, which you also copy on the fist board. When they mate you at some point on one board, you copy this immediately, winning the other game.
This strategy won't work for <object type="image/svg+xml" data="/ox-hugo/20200414104653-blog_posts_c7ea9bf60399dae5f34e826d4f1a8ecc0a4a6030.svg" class="org-svg"> Sorry, your browser does not support SVG.</object>. Here we would have to decide at the beginning which game we have a winning strategy in, then choose that one.
In logic, this means that the sequent <object type="image/svg+xml" data="/ox-hugo/20200414104653-blog_posts_8964387a593f0de3a11f74446080e77066b64d2e.svg" class="org-svg"> Sorry, your browser does not support SVG.</object> is provable, but <object type="image/svg+xml" data="/ox-hugo/20200414104653-blog_posts_1e6005344886e5204b0108a5d3703657626bc38c.svg" class="org-svg"> Sorry, your browser does not support SVG.</object> isn't.
So far, we've only looked at the two forms of conjunction. There is also two forms of disjunction, given simply by <object type="image/svg+xml" data="/ox-hugo/20200414104653-blog_posts_332bfcca70f28fa5e5f48759a18df39665e5212c.svg" class="org-svg"> Sorry, your browser does not support SVG.</object>, <object type="image/svg+xml" data="/ox-hugo/20200414104653-blog_posts_b6e991d197297486fb377f8b2f7a71d7df9a0212.svg" class="org-svg"> Sorry, your browser does not support SVG.</object>. We could restate the above discussion as "<object type="image/svg+xml" data="/ox-hugo/20200414104653-blog_posts_67c4e3051ed267d97a37f2525aea5d5118ea2b30.svg" class="org-svg"> Sorry, your browser does not support SVG.</object> is not provable, but $is". This means we have a form of excluded middle, but another form of excluded middle doesn't hold.
Now what is the meaning of a general sequent of the form <object type="image/svg+xml" data="/ox-hugo/20200414104653-blog_posts_b995dd0c8fb474bb2182224fbeab583cfacd8a49.svg" class="org-svg"> Sorry, your browser does not support SVG.</object>, where both <object type="image/svg+xml" data="/ox-hugo/20200414104653-blog_posts_82b14cc542ef22dba87993b12dd6d6d310f947d7.svg" class="org-svg"> Sorry, your browser does not support SVG.</object> and <object type="image/svg+xml" data="/ox-hugo/20200414104653-blog_posts_a33a2d6e25b53b1938ccfc129cc9544b9628375b.svg" class="org-svg"> Sorry, your browser does not support SVG.</object> are multisets. We can interpret such a sequent as asserting the existence of a strategy for the game <object type="image/svg+xml" data="/ox-hugo/20200414104653-blog_posts_3415bd826597d728f3ee0489dbfa6c59ba7f9f84.svg" class="org-svg"> Sorry, your browser does not support SVG.</object>. A proof is supposed to identify a specific strategy for the game. This also means that any sequent can be replaced by a one-sided one, which means linear logic can be expressed all in terms of one-sided sequents (which is indeed true).
Now we can think about the lack of contraction - we can examine simply the fact that <object type="image/svg+xml" data="/ox-hugo/20200414104653-blog_posts_4e379c847bf45683840230c2b93ef93f20c24be8.svg" class="org-svg"> Sorry, your browser does not support SVG.</object> is not a provable sequent.
To prove this sequent, we would want a strategy for <object type="image/svg+xml" data="/ox-hugo/20200414104653-blog_posts_404495e2a205415c8b6fc83ff9a40bce2b9ef3c4.svg" class="org-svg"> Sorry, your browser does not support SVG.</object>. We can think of this again in the case where <object type="image/svg+xml" data="/ox-hugo/20200414104653-blog_posts_a7d92cc965ef976b84b9370a6f429d98bc7d2fb9.svg" class="org-svg"> Sorry, your browser does not support SVG.</object> is chess. Imagine that instead of two games, there are three, two where you are black. You can only respond on whatever black board where your opponent just moved as white, or move as white on the board where you are white (forcing your opponent to respond there). And when you respond as black, your opponent can switch to the other black board. You can only mirror one of these onto the game where you're white, so the strategy-stealing trick no longer works.
On the other hand, weakening _is_ valid in this semantics. We do have a strategy for the game <object type="image/svg+xml" data="/ox-hugo/20200414104653-blog_posts_afddd41d83bccf2bec783f5e313950c75d967c4b.svg" class="org-svg"> Sorry, your browser does not support SVG.</object>. Here you have two white boards and one black, and you can simply ignore the white board you don't need, since you now have full control over which board you move on.
This is all written out in Blass: A game semantics for linear logic.
Universal properties and Compositionality [universal-properties-and-compositionality]
Universal properties and Compositionality [universal-properties-and-compositionality]
Continuing the train of thought from this tweet, I compare and contrast two perspectives on the philosophy of category theory: that it's about describing how things can be composed of other things ("compositionality"), and that it's about describing things in terms of their transformations into other things ("universal properties").
Left adjoints preserve colimits. [left-adjoints-preserve-colimits]
Left adjoints preserve colimits. [left-adjoints-preserve-colimits]
Let's prove a classical theorem (Emily Riehl's favorite!) from category theory: Right adjoint functors preserve limits. So let's assume we have categories C,D, functors F: C \to D, G: D \to C, and a natural bijection C(G(a),b) \cong D(a,F(b)). Let's also fix a diagram X: I \to C from some index category I. Now recall that a limit of X is an object \lim X, equipped with maps \pi _i: \lim X \to X(i), so that every triangle
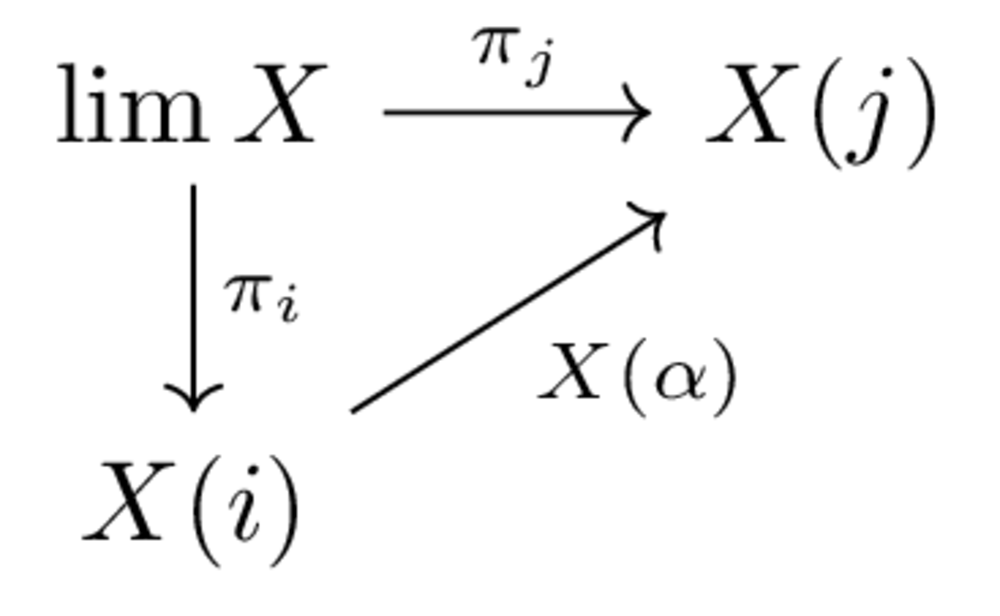
commutes, and so that, given another set of data (p, f_i: p to X(i)) with the same property, there is a unique map f: p \to \lim X so that f_i = \pi _if.
(I am sort of assuming you already know about limits, and just writing the definition above for convenience).
The proof idea, very weakly formulated, is that the adjunction lets us control maps into F(b), and the universal property of the limit is precisely about maps into F(\lim X).
Let's first make completely precise the claim: it is that, supposing (\lim X, \pi _i) forms a limit of X, then also (F(\lim X), F(\pi _i)) forms a limit of F \circ X. Note that this makes sense - F(\pi _i) really is a map from F(\lim X) to FX(i).
Now let's fix another cone (p,f_i) on (F\lim X, F(\pi _i)). We are attempting to construct a map p \to F(\lim X). This is equivalent to a map G(p) \to \lim X. We're going to construct _that_ map by constructing maps G(p) \to X_i. Where do we get those maps? We apply the adjunction again - they are simply the mates of the maps p \to F(X_i) we started with. Now we need to confirm that the map p \to F(\lim X) actually does make the desired triangles commute.
This follows from naturality of the adjunction, using the same property for G(p) \to \lim X: Consider the composite p \to F(\lim X) \to F(X(i)). By naturality of the adjunction (with regard to postcomposition), the mate of this map is the composite G(p) \to \lim X \to X(i). By construction, this equals the input map G(p) \to X(i), which is the mate of the original f_i: p \to F(X_i). Hence the composite has the same mate as f_i, so equals it.
The second thing we need to prove is that this map is unique with this property. We can do this by noting that, given two distinct map with this property, their mates G(p) \to \lim X are distinct (because the correspondence is bijective), and both have this property (by the same argument used above). This establishes the claim.
The homotopy theory of groups [the-homotopy-theory-of-groups]
The homotopy theory of groups [the-homotopy-theory-of-groups]
Context: Krause and Nikolaus: Group Theory for Homotopy Theorists (pdf). Krause and Nikolaus develop group theory using model categories (well, one model category). This is obviously a joke, but I think it _is_ a very useful pedagogical joke. So I'm going to go through it and try to explain what's happening.
A category of computable functions with runtime [category-of-computable-categories-with-runtime]
A category of computable functions with runtime [category-of-computable-categories-with-runtime]
See: Giorgios Bakirtzis and Christian Williams: Turing Categories. Turing Categories describe _computability_. I want to find a category to work with _complexity_ instead. This is a stab at it. Fix a universal Turing machine and an encoding of the natural numbers. Of course, this lets us speak of _computable_ functions \mathbb {N} \to \mathbb {N} (and these don't depend on the choice of Turing machine). But fixing a specific machine also lets us speak of the _runtime_, in steps, of a program p with input n \in \mathbb {N}. Write p(n) = m if p(n) eventually terminates with output m, and write T(p,n) = t if it takes t steps.
Now we want to define a category as follows:
- The objects are subsets of the natural numbers.
- The maps A \to B are equivalence classes of programs under an "asymptotic equivalence" relation.
- The composition is "the obvious thing".
What I mean by asymptotic equivalence is this: the two programs halt on the same inputs, produce the same outputs, and run in the same amount of time up to a constant factor. To be more precise, p \lesssim p' : A \to B if there exists a constant C so that, when p(n) = m and T(p,n) = t, p'(n) = m and T(p,n) \leq Ct. Then p \sim p' if p \lesssim p' and p' \lesssim p.
This corresponds to our natural definition of "same behaviour, and same O-class".
Now, we want to construct the composition pp' simply to have pp'(n) = p(p'(n)) and T(pp',n) = T(p',n) + T(p,p'(n)). (This means that if p'(n) halts with output m, and p(m) halts with output k, then pp'(n) halts with output k, and has the runtime described above, otherwise it doesn't halt). It's not completely trivial that this is possible - essentially, the "overhead of composition" must be smaller than the runtime of the larger of p and p'. We must add this as a requirement to our Turing machine - luckily, this seems to be satisfied by most sane models of computation.
Call the category so defined \mathrm {Comp}.
Localizations of categories of dynamical systems [localizations-categories-dynamical-systems]
Localizations of categories of dynamical systems [localizations-categories-dynamical-systems]
Cheap nonstandard analysis [cheap-nonstandard-analysis]
Cheap nonstandard analysis [cheap-nonstandard-analysis]
Terry Tao: A cheap version of nonstandard analysis. MathOverflow: Does Cheap Nonstandard analysis take place in a topos? (Answer: Yes, but an elementary topos, not a Grothendieck topos).
This is partially a summary of Tao's blog post, partially a small discussion of way LEM fails for cheap nonstandard reals.
Jensen-Shannon divergence is compositional [jsd-as-enrichment]
Jensen-Shannon divergence is compositional [jsd-as-enrichment]
Let \mathsf {FinStoch} be the category of finite sets and stochastic matrices. Given two stochastic matrices, f_1,f_2: X \to Y, we can define their **Jensen-Shannon distance** as d(f_1,f_2) := \sup _x \sqrt {\operatorname {JSD}(f_1(x),f_2(x))}, where JSD is the Jensen-Shannon divergence. It's a standard result that the root of JSD defines a metric on the space of probability measures - hence the above defines a metric on the set \mathsf {FinStoch}(X,Y). My aim here is to show that _this gives an enrichment of \mathsf {FinStoch} in the category \mathsf {Met} of metric spaces and **short**, i.e distance nonincreasing, maps_
The content of this statement is that the composition map
\mathsf {FinStoch}(X,Y) \otimes \mathsf {FinStoch}(Y,Z) \to \mathsf {FinStoch}(X,Z) is a short map. The monoidal structure on \mathsf {Met} that we're considering is given by the "1-metric", i.e
d_{X \otimes Y}((x,y),(x',y')) = d_X(x,x') + d_Y(y,y')This has the convenient property that a map is short if and only if it's "short in each variable separately". In other words, we must show that the map
f \circ - :\mathsf {FinStoch}(X,Y) \to \mathsf {FinStoch}(X,Z)is short for each f, and that the map
- \circ f : \mathsf {FinStoch}(Y,Z) \to \mathsf {FinStoch}(X,Z)is short for each f.
Compositionality for Transfer Learning [compositionality-for-transfer-learning]
Compositionality for Transfer Learning [compositionality-for-transfer-learning]
_Transfer learning_ is the idea that, after a machine learning system (or a non-machine learning system, for that matter, like a human) has learned to solve some problem, it should be able to _transfer_ this knowledge to solving similar problems. Humans are pretty good at this, at least compared to current ML systems, which tend to suck.
Why do we expect transfer learning to work? It seems that, in general, we expect that the solution to a task can be _decomposed_ into several pieces, some of which will still be useful for the related task. As an example, suppose we teach a self-driving card to drive to a given place, using a map of the local area and camera input. If we could open up the resulting algorithm, we may expect to find "subroutines" corresponding to
1. Breaking down the visual input into objects. 2. Maintaining/updating an internal memory with this data. 3. Using this data to locate itself on the map 4. Plotting a route on the map between two points 5. Executing a route while driving correctly (i.e not breaking the law, not causing crashes).
If we now want this system, instead, to locate and follow a car with a specific license plate (or something), we would expect that most of these routines, except perhaps 3 and 4, would still be useful. It would not have to learn all over again how to recognize other cars and involve crashes.
In other words, we expect transfer learning to happen because of _compositionality_. To introduce some symbols, we are trying to learn a function f: X \to Y from observations to decisions. The target behavior is really a function of some high-level description of the system, as understood by humans, i.e it factors as X \overset {p}{\to } \bar {X} \overset {f'}{\to } Y. If the system manages to learn p as well as f', then if we swap out the task with another one, which is also specified on the same abstract level, g': \bar {X} \to Y, the system will have less to do - a lot of the parameter space is already in the right configuration.
Of course, if you already knew how to compute the high-level representation \bar {X}, you mostly wouldn't need machine learning. However, when we view the problem from this angle, it seems one way to get more transfer learning is to look for learning algorithms that output "decomposed" models, so that we can try to separate the abstraction X \to \bar {X}, from the "task-specific logic" f': \bar {X} \to Y.
One way to do this is to find a class of related tasks, \{f_i:X \to Y_i | i = 1 \dots n\}, which we feel share a common abstraction. Then we can pick some set \bar {X} and try to train n+1 models - one going from X \to \bar {X}, the others going from \bar {X} \to Y_i. We give each of these algorithms the average loss across all the tasks as the loss. Then the "high-level models" \bar {X} \to Y_i try to make use of the low-level data as best they can, while the "abstraction" model X \to \bar {X} tries to create an abstraction which is useful to all the high-level models.
Stochastic Stalks [stochastic-stalks]
Stochastic Stalks [stochastic-stalks]
The Ax-Grothendieck theorem [ax-grothendieck-model-theory]
The Ax-Grothendieck theorem [ax-grothendieck-model-theory]
The Ax-Grothendieck theorem says the following: Let f: \mathbb {C}^n \to \mathbb {C}^n be a polynomial function. If it's injective, then it's surjective as well.
Here's how to prove it:
1. The statement can be formulated as a first-order statement in the language of fields 2. If a statement like that fails for \mathbb {C}, there's a disproof in the first-order theory of algebraically closed fields of characteristic zero. 3. Such a proof is _finite_, so it only uses finitely many of the assumptions p \neq 0 - hence the theorem also fails in algebraically closed fields of sufficiently high characteristic. 4. Hence it fails in the algebraic closure of \mathbb {F}_p. The specific counterexample is in some finite extension of \mathbb {F}_p, which is a finite field. But clearly the theorem is _true_ for finite fields, just by counting.
I think this is a pretty cool proof - it uses model theory in a really surprising way, and the step where you use the fact that _proofs are finite_ is just totally bonkers.
Notes from "Persistent Homotopy Theory" [jardine-persistent-htpy]
Notes from "Persistent Homotopy Theory" [jardine-persistent-htpy]
My notes from Persistent Homotopy Theory by JF Jardine. The goal of the paper is to study "filtered spaces". By this is meant in general something like an assignment s \mapsto X_s of a "space" or simplicial set to each nonnegative real s \in [ 0,\infty ). A prototypical example is the Vietoris-Rips complex of a metric space, V_s(X).
The idea being pointed towards is some sort of modification of model category theory to make ideas from persistent homology work more nicely. The main example considered is an inclusion of VR-complexes V_s(X) \to V_s(Y) coming from an incusion of datasets X \subset Y where all the points in Y are "close to" ponts in Y. In this situatio V_s(X) \to V_s(Y) is not generally a homotopy equivalence or anything like tat, but it's still a bit "equivalency" - we would like to understand howthis works, and how this plays into classical model category theory.
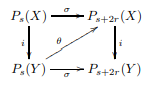
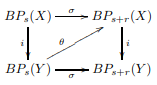
Complexity theory, probability [complexity-theory-probability]
Complexity theory, probability [complexity-theory-probability]
The zero-one laws of Kolmogorov and Hewitt–Savage in categorical probability [zero-one-laws-paper]
The zero-one laws of Kolmogorov and Hewitt–Savage in categorical probability [zero-one-laws-paper]
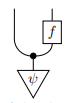
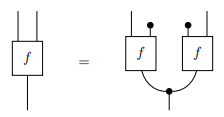
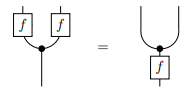
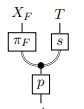
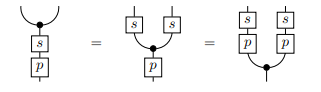
Bivariate Causal Inference [bivariate-causal-inference]
Bivariate Causal Inference [bivariate-causal-inference]
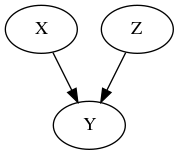
How to Make A Website [2020-02-28-how-to-make-a-website]
How to Make A Website [2020-02-28-how-to-make-a-website]
Here's what goes into a website.
- A server (hardware).
- The software which runs on the server, also called a server.
- A domain (optional)
- An SSL certificate (technically optional but highly recommended)
I will explain what these terms mean, and how to get your own stuff set up. Please note that this is a guide for people who want to do everything from scratch. There are plenty of easier ways to set up a website. For instance:
- Any of a number of blogging systems, like wordpress.com, which will also help you hook up your own domain.
- nearlyfreespeech.com - an extremely cheap option if you want to do some things yourself. If your website is just a collection of static pages, this is an easy way to put it on the internet.
Frequentist Statistics and Compositionality [2020-02-27-compositional-frequentism]
Frequentist Statistics and Compositionality [2020-02-27-compositional-frequentism]
Time-saving blurb: This essay thingy eventually ends without any useful conclusion (I don't manage to figure out how to make something compose). Also, it's not clear that what's here is particularly deep even if it could be made to work, which it hasn't.