Example [efr-IMZ3]
Example [efr-IMZ3]
Consider the Markov prefibration \mathsf {TychDiffStoch}^\to \to \mathsf {TychDiffStoch}. Equip this with the section T(X) = X \otimes X \xrightarrow {\pi _0} X - this described discrete-time systems (whose update is required to be smooth in the input and present state). This is clearly a symmetric monoidal functor and thus defines a systems theory. Note that this is completely different from the ordinary tangent bundle, despite the coincidence of notation.
Let m_1: TS_2 \otimes X_1 \leftrightarrows Y_1 and m_2: TS_2 \otimes X_2 \leftrightarrows Y_2 be two bisystems in this theory. As in § [efr-SREZ], we may define a parameterized lens (TS_1 \& TS_2) \otimes (X_1 \oplus X_2) \leftrightarrows (Y_1 \oplus X_2), denoting by \oplus the coproduct in lenses, and by \& the Markov structure defined in Corollary [efr-FT8J]. Observe that TS_1 \& TS_2 is simply the indexed set (S_1 \coprod S_2) \otimes S_1 \otimes S_2 \to S_1\otimes S_2. There is an obvious indexed map from this to T(S_1 \otimes S_2) = S_1 \otimes S_2 \otimes S_1 \otimes S_2, given by (\operatorname {inl} s_1', s_1,s_2) \mapsto (s_1', s_2, s_1, s_2) and (\operatorname {inr} s_2', s_1, s_2) \mapsto (s_1,s_2',s_1,s_2). In words, we receive an update either to the S-state or to the S'-state. We apply this update to the relevant state and leave the other alone. This defines a lens T(S_1 \otimes S_2) \leftrightarrows T(S_1) \& T(S_2), which we may compose with the above to obtain a bisystem T(S_1 \otimes S_2) \otimes (X_1 \oplus X_2) \leftrightarrows Y_1 \oplus Y_2. Let us denote this by m_1 \oplus m_2.
This has very much the same flavor as the external choice for open games, although we will not develop the theory of this operation in detail here.
Now, given a smooth (deterministic) map F: P \times X \to Y, where P,X,Y are smooth manifolds (not merely diffeo-toplogical spaces), we obtain a lens T^*(F): {T^*P \choose P} \otimes {T^*X \choose X} \leftrightarrows {T^*Y \choose Y}, where T^*(-) denotes the cotangent bundle. (This does not, prima facie, make sense for a general diffeo-topological space).
Let us take as given some family of lenses T(S) = {S \otimes S \choose S} \leftrightarrows {T^*S \choose S} for various S. Such an operation amounts to choosing a way of updating s \in S given a cotangent vector---hence we can see it as an optimization algorithm. One example of such would be gradient descent, which given a choice of Riemann structure on S, takes a step of a given length in the direction which most quickly decreases the given covector.
(It should be noted that there are more complicated optimization strategies which don't fit this particular pattern - for example, momentum algorithms have to maintain some extra internal state other than s \in S. But let's stick with this pattern for this example). Note also that we're not assuming the optimizers are a natural transformation or anything like that.
Now we are ready to build the neural network architecture known as a generative adversarial network, or GAN (Reference [gan-paper]). Let us first describe the idea. Our goal is to generate additional samples from some distribution, given a set of existing samples---for example, our goal may be to generate more pictures in the same style as an existing corpus. Suppose our data is of type X, and let d: I \to X be the data distribution. We fix some latent distribution \lambda : I \to L, where L is any space of our choice---usually, L is \mathbb {R}^n and \lambda is a Gaussian. Finally we choose two neural networks, the generator G: P_G \otimes L \to X, and the discriminator D: P_D \otimes X \to \mathbb {R}. The goal of the discriminator is to discriminate real samples from the data from generated samples, by providing a low value on the generated samples and a high value on the true samples.
The training process now goes as follows: for each step of training, we either sample from the latent distribution, and have the generator use this to generate a sample, or draw a sample from the data distribution (choosing between these with some probability p). Then in either case, we have the discriminator score the generated sample. If the sample was generated by the generator, the discriminator's loss is equal to its output, otherwise it is equal to -1 times its output. We update the discriminator according to the gradient of this loss (minimizing it), and update the generator (if we are in the branch where it was run) according to the negative of the gradient of this loss with respect to the generator parameters---this amounts to doing a gradient descent update on the generator for the negative of the discriminator loss.
We can represent this schematically using the following tape diagram (see Reference [tape-diags-monoidal-monads]):
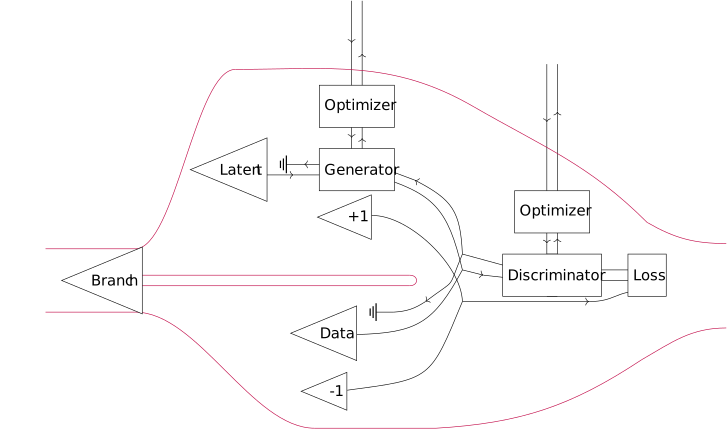
The two "tapes" branching off at the start represent two maps (bisystems) composed by \oplus , while the backwards wires indicate the flow of the gradients. The ground symbol indicates a value being discarded. Note that the theory of tape diagrams has only been developed formally for distributive categories, and for essentilly the same reason as in § [efr-SREZ], we do not have distributivity in this case. However, the interpretation of this diagram is still unambiguous---distributivity is required to make tape diagrams complete, not to make them sound. Concretely, if we tried to represent the tensoring of this system with another system, we would have no way of doing it, but if the category was distributive we could do so by adding this additional system to each of the branches. Still, the figure is best viewed as a visual aid rather than a formal representation.